Session 8: scalable oversight and "whose values?"
Session 7 showed how labs scale feedback by replacing human raters with AI (RLAIF, Constitutional AI). That sharpens a problem rather than solving it, and forces a second, normative question the engineering cannot dodge.
This session's sub-sessions: 8.1 scalable oversight · 8.2 four ethical lenses · 8.3 Ubuntu and relational ethics · 8.4 whose values?
What we'll cover
Scalable oversight concerns training and evaluating systems on tasks their unaided supervisors cannot reliably judge. We examine several proposed methods and experiments that test generalisation beyond weak supervision.
The supervision gap
Reliable evaluation becomes harder when the system can produce answers beyond the supervisor’s expertise.
Training signals are imperfect evidence of the behaviour we want. A model may generalise beyond its supervisors, but their errors can also persist or be amplified. Scalable oversight asks how to train and evaluate a stronger system when unaided humans cannot reliably assess its answers. The weak-to-strong results below make the distinction between possible generalisation and reliable oversight concrete.
Unaided human checking at the frontier
For a 10,000-line refactor, a novel mathematical proof, or a subtle security audit, a human may be unable to tell a correct answer from a confident wrong one. Two things then go wrong at once. The signal becomes noisier, which can limit what the model learns. Worse, optimising against a judge who can be fooled actively rewards persuasiveness over correctness (the Goodhart dynamic of Session 3, now aimed straight at the overseer). The signal does not just fade where we need it most; it can point the wrong way.
Supporting a limited overseer with tools, assistants or structured tasks may improve the feedback they provide. The methods below propose different forms of support and different ways to test their reliability.
Studying the gap before we have superhuman models: sandwiching
There is an obvious methodological trap: the systems we most need to oversee do not exist yet, so we cannot experiment on them. Sandwiching, proposed by Cotra (2021) and operationalised by Bowman et al. (2022), is the field's way around it. Pick a task on which a current model is already more capable than a non-expert human, but for which a separate expert (or ground-truth answer) can score the result: medical questions for a layperson, say, or code review for a non-programmer. The non-expert, equipped with the oversight protocol you want to test, tries to supervise the model toward the expert's answer. If they succeed, the protocol has scaled a weak overseer's judgement; if they fail, you have found a real limit, now, on hardware you have.
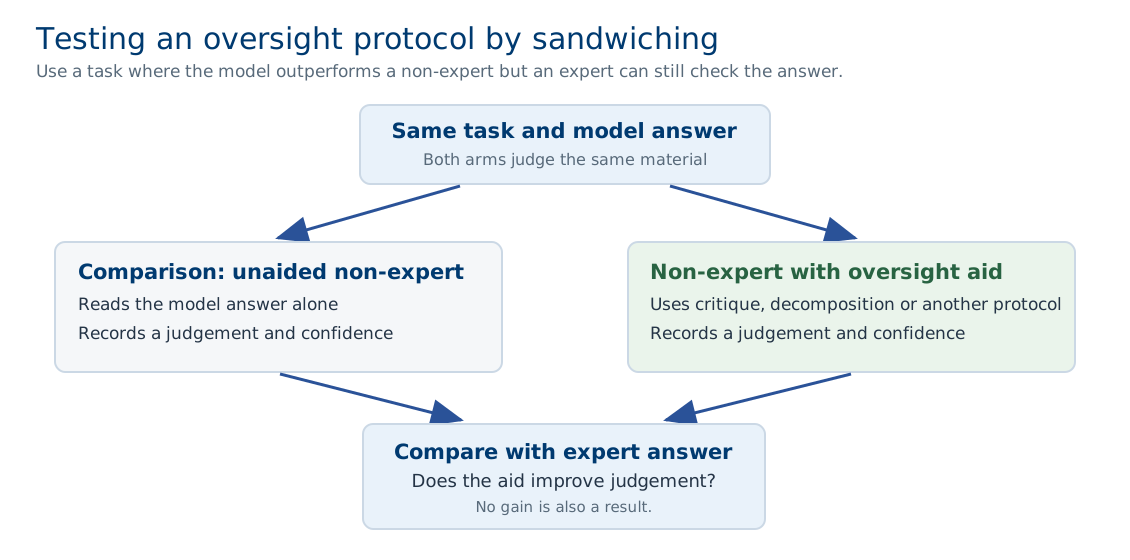
Comparing oversight protocols
Sandwiching turns "scalable oversight" from a slogan into something measurable. It lets a lab compare debate against plain Q&A, or AI-assisted critique against unaided judgement, on the same task, and report which protocol closes more of the non-expert-to-expert gap. Much of the empirical work in this area is now reported in this frame, and it is a good source of student projects (Week 7, after Session 13): take a sandwiching task in a language or domain that the published work ignores, and measure whether the protocol still holds.
Five ways to amplify a limited overseer
The proposals differ in how they extend the overseer, but share one aim: keep the human anchored to the truth while the model does the heavy lifting.
Task decomposition (iterated amplification)
Break a hard question into sub-questions a human, helped by model assistants, can answer, and recurse. Christiano et al. (2018) formalise this as amplifying a weak human expert by letting the expert consult copies of the model being trained. The bet: hard judgements decompose into checkable pieces. The risk: the decomposition may not be faithful, and small per-step errors compound up the tree.
Recursive reward modelling
Leike et al. (2018) propose using reward modelling to train agents on easy tasks, then using those agents to help humans evaluate harder ones, climbing a ladder of capability. Each rung is checkable using the rung below, and may inherit its errors; whether those errors accumulate or are dampened up the ladder is the open question.
Debate
Irving et al. (2018) pit two strong models against each other to argue opposing answers before a weaker judge. The hope: defending a falsehood is harder than exposing it, so an honest strategy wins even when the judge could not solve the task alone.
AI-assisted evaluation
Saunders et al. (2022) train models to critique outputs, to surface the flaws a human would otherwise miss. The human stays the judge, but with a sharper lens. The critic itself can miss or fabricate problems, so it assists rather than replaces.
AI feedback at scale (RLAIF / Constitutional AI)
Bai et al. (2022) replace most human labels with model-generated feedback steered by a written constitution (Session 7). This scales oversight cheaply, but relocates the hard question to "whose constitution, and who wrote it?" Sub-session 8.4 takes that up.
Notice the two limits that recur across the list. The decomposition methods assume hard judgements break cleanly into easy ones; the competitive and assistance methods assume the human judge cannot be manipulated by a sufficiently capable arguer. Debate leans on the second assumption most heavily, and it is also where it is most contested: Barnes and Christiano’s (2020) "obfuscated argument" problem shows a dishonest debater can sometimes bury a flaw in a sub-tree too large for the judge to check, so persuasion can still beat truth. These are the open theoretical questions of the field, not implementation bugs to be patched.
Weak-to-strong generalisation
The limits of naive weak supervision
Burns et al. (2023) study the analogy head-on. If a future human is a weak supervisor of a strong model, what does naive supervision get you? They stand in for the pair by fine-tuning a strong model (say GPT-4) on labels produced by a much smaller model from the same family with roughly GPT-2-level capability, and ask how much of the strong model's latent capability the weak labels elicit. The finding cuts both ways: the strong model generalises past its noisy supervisor, though it still imitates some of the weak labels' mistakes, and for the largest students on NLP tasks it often recovers more than half of the performance gap between the weak supervisor and a strong model trained on ground-truth labels. But a real gap remains; naive weak supervision leaves capability, and with it alignment, on the table. Closing that gap, so a weak overseer can elicit a strong model's full competence and not a degraded copy, is the concrete form the superalignment problem takes.
Burns et al. define performance gap recovered (PGR) as
Here \(S_{\text{weak}}\) is the weak supervisor’s score, \(S_{\text{w2s}}\) is the strong student’s score after training on weak labels, and \(S_{\text{strong ceiling}}\) is the score of the strong model trained on ground-truth labels. The denominator must be non-zero. For the largest students on NLP classification tasks, PGR is often above 0.5. On the ChatGPT reward-modelling task, naive weak supervision usually recovers roughly 10% of the gap and almost never exceeds 20%, even for relatively small supervisor–student compute gaps. This is the preference-prediction task used in RLHF; the study does not run the subsequent RL step.
Limits of the five methods
Each method amplifies human judgement; none removes the human's vulnerability to a capable enough system that wants to exploit it. A debate judge can still be dazzled; a decomposition can still hide a decisive error in an unchecked branch; AI feedback inherits whatever the feedback model gets wrong. The methods raise the bar an overseer can clear, which is real and valuable, and they give us something to measure with sandwiching. They do not yet provide a guarantee that scales without limit.
Known failure modes
Debate, amplification, recursive reward modelling, AI-assisted critique and weak-to-strong are live research directions with known failure modes: collusion, obfuscated arguments, judges that anchor on fluency, critics that fabricate. Read them as the current state of an unsolved problem. This is why the course also pursues a complementary bet: instead of only watching a model's outputs, look inside its computation (interpretability, Session 13), so oversight does not depend solely on a human grading text a model may have learned to game.
The researchers who built these methods are hedging too. Paul Christiano co-authored two of the papers on this page, the debate proposal and iterated amplification, and in August 2026 he returned as executive director of the Alignment Research Center, which is betting on something else. He locates the difficulty a level below oversight: “I (and many others) think this incomprehensibility is at the root of the alignment problem. Because we don’t understand why a neural network works, we have no idea what changes to the input distribution might cause it to stop working.” A behavioural loss function, he wrote in a reply below the post, “cannot depend at all on how the model behaves out of distribution”, because behaviour on the distribution you happened to test is the only evidence it ever gets. The five families on this page all rely on behavioural signals of this kind. He frames ARC’s search for mechanistic explanations as a backup plan for the case where the current approaches break down before we reach superhuman systems. Note what he does not say: the post makes no argument that amplification or debate was a mistake, and does not mention them. It is a researcher hedging his own agenda, and Session 13 examines mechanistic explanations.
Oversight in low-resource languages
Assumptions behind every protocol
Every protocol here assumes an overseer who can at least understand the task and follow the arguments, usually in the relevant language, and checking a protocol needs experts or trusted labels. A sandwiching study needs non-expert overseers and a ground truth to score them against, from experts or from labelled data; a constitution encodes the principles of whoever wrote it. For most African languages the model is already weaker (the data gap of Session 2.3), expert evaluators and labelled benchmarks are scarcer, and the published oversight results were almost all measured in English. So the supervision gap is largest where the tools to close it are least developed. "Can a non-expert reliably oversee a model in isiZulu?" is both a fair exam question and an open research problem, and it connects directly to whose values the oversight is steering toward (8.4) and to how we evaluate any of this (Session 11).
Questions to bring to class
- State the supervision gap in your own words, and give a task on which you are a competent grader but not a competent producer, and one where you are neither.
- Sandwiching needs a task where a model beats a non-expert but an expert can still score it. Propose one in a domain you know, and say what could go wrong with using it to certify an oversight method.
- Debate and weak-to-strong make opposite bets about a weak judge facing a strong model. Which do you find more convincing, and what evidence would change your mind?
- Pick one method above and explain precisely how a capable, misaligned model could still defeat it.
Readings
Mandatory readings
• Burns et al. (2023), "Weak-to-Strong Generalization" (arXiv:2312.09390): read pp. 1–7, the setup and the headline result. ≈3,800 words. The paper runs to 49 pages: 19 of main text, then references and 22 pages of appendices.
• Irving, Christiano & Amodei (2018), "AI Safety via Debate" (arXiv:1805.00899): read §1 and the opening of §2, the debate game itself. ≈1,400 words.
Total mandatory load: ≈5,200 words.
Optional readings
• Irving et al., §5 (≈2,800 words): ten reasons to worry about debate, written by its proposers. The most useful part of the paper for a safety course, and the first thing to read if you go further.
• Bowman et al. (2022), "Measuring Progress on Scalable Oversight" (arXiv:2211.03540): the sandwiching paradigm. ≈7,400 words.
• Christiano, Shlegeris & Amodei (2018), "Supervising Strong Learners by Amplifying Weak Experts" (arXiv:1810.08575): iterated amplification. ≈4,400 words.
• Leike et al. (2018), "Scalable Agent Alignment via Reward Modeling" (arXiv:1811.07871): recursive reward modelling. ≈13,500 words.
• Saunders et al. (2022), "Self-critiquing Models for Assisting Human Evaluators" (arXiv:2206.05802): ≈8,800 words.
• Bai et al. (2022), "Constitutional AI" (arXiv:2212.08073): taken up in Session 7.
Next
Suppose oversight worked perfectly. You would still have to decide what you are overseeing toward. "Aligned" is a relation to a target, not a property a model has on its own. Sub-session 8.2 introduces the four philosophical lenses for reasoning about that target; 8.3 brings in Ubuntu and relational ethics; 8.4 shows the choice is also a mathematical constraint.